What Are Application Management Services (AMS)? A Guide
Oct 08, 2026 / Updated: Oct 08, 2026
If you run AMS, more of your tickets now follow a change: a transport from the S/4HANA program, a quarterly upgrade, or a new AI tool reading and writing core data. Application management services were designed for a steadier estate, and the gap shows up as tickets bouncing between teams while orders sit unposted.
Key Takeaways
- Application management services (AMS) are the ongoing support, maintenance and improvement of business applications such as SAP after go-live, run by an in-house team, a provider, or both.
- AMS covers incidents and problems, service requests and access, change and release, monitoring, platform operations and small enhancements.
- AMS is typically organized by support tier and system team, and contracts are shifting from effort-based pricing toward outcome-based agreements.
- Migrations, upgrades and new AI systems drive a growing share of AMS workload, and every handoff between teams restarts the investigation.
- AI agents help AMS teams keep pace by investigating across systems, scoring change risk before CAB and executing approved fixes, with people approving every change.
What are application management services (AMS)?
Application management services (AMS) are the ongoing support, maintenance and improvement of business applications after they go live, delivered by an in-house team, an outside provider, or a mix of both. You’ll also see the same work called application managed services or managed application services.
AMS starts where the implementation project ends. The systems in scope are the ones the business runs on: SAP ECC and S/4HANA, Oracle, Salesforce, Workday, and the custom applications and integrations built around them. An AMS team answers for whether those systems do their job, which in business terms means orders post, invoices go out and payroll runs on time.
Day to day, AMS work looks like restoring a failed interface between SAP and a warehouse system, giving a finance user the role they need for month-end close, applying an SAP Note, tuning a report that slows every Monday morning, or building a small change to a pricing routine. In SAP landscapes the whole function is usually just called SAP AMS.
What functions do application management services cover?
Every AMS scope, in-house or outsourced, is built from the same seven functions. What changes between organizations is who owns each one and how much of it runs on people versus automation.
Function
What it includes
Typical owner
Incident management
Restoring service after failed jobs, short dumps, stuck interfaces and errors users report
L1 triage, L2 functional and technical analysts
Problem management
Finding and removing the root cause of recurring incidents
L2 and L3
Service requests and access
Role assignments, master data corrections, how-to questions
L0 self-service, L1, security team
Change and release
Transports, change advisory board (CAB) reviews, SAP Notes, upgrades
Change manager, Basis, developers
Monitoring
Background jobs, interfaces and queues, system performance
Basis and middleware teams
Platform operations
Basis administration, system copies, patching, capacity
Basis team
Enhancements
Small developments, report changes, configuration changes
L3, ABAP developers, functional consultants
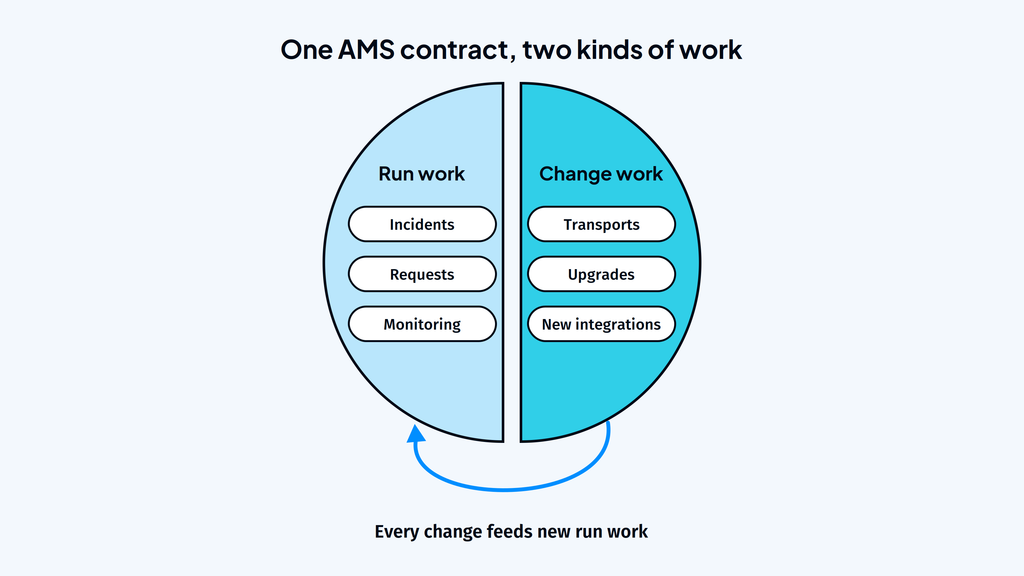
Every AMS contract splits into run work and change work
Run work is everything it takes to operate the system as it stands: resolving incidents, fulfilling requests, and watching jobs and interfaces. Change work alters the system itself through transports, Notes, upgrades, enhancements and every new integration.
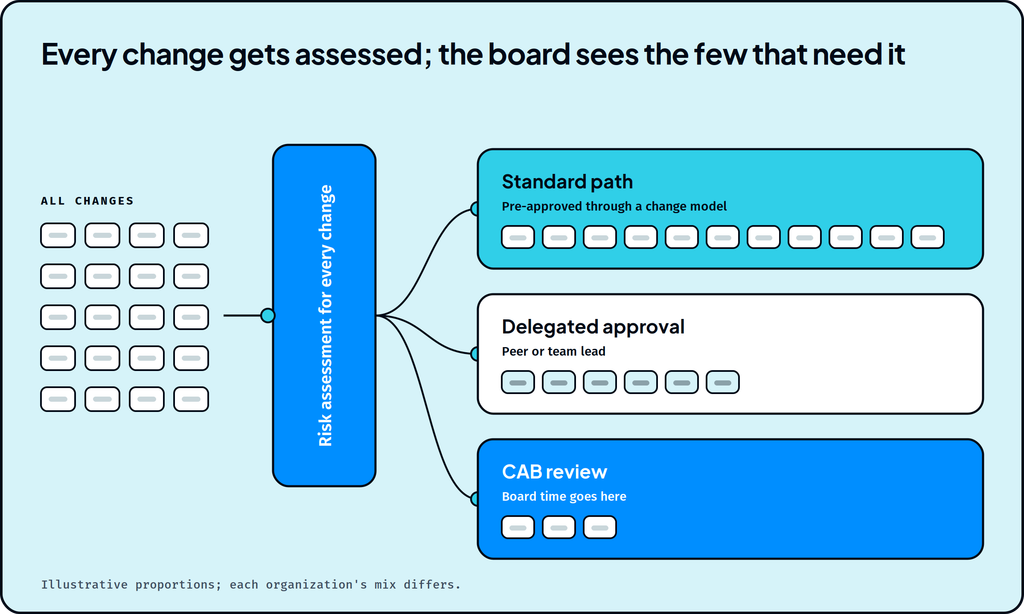
Most AMS teams were sized and priced around run work, with change handled as a project or a block of enhancement hours. That balance is shifting because change creates run work. Each transport increases the chance of an incident, and each newly connected system adds another place for one to start. The change advisory board is where that risk gets reviewed, and it’s also where many AMS teams feel the volume first.
How are application management services delivered?
Most enterprises follow one of three common patterns. The right one depends on the estate, the skills in-house and the contract, and each handles change volume differently.
Model
Strengths
Watch-outs
Often suits
In-house
Deep process knowledge, direct control of priorities
Hard to staff around the clock and to hold niche skills like Basis and middleware
Estates with steady change volume and a strong internal SAP team
Provider
Scale, follow-the-sun coverage, broad skills on demand
Process knowledge sits with the provider; every scope boundary adds a handoff
Organizations that want predictable cost and coverage
Hybrid
The business keeps critical knowledge and decisions while the provider absorbs volume
Two queues and two sets of SLAs to reconcile
Large estates with a mix of internal and partner skills
AMS pricing has long tracked effort, and outcome-based models are gaining ground
Common pricing models include dedicated FTEs, time and materials, ticket-based pricing, a fixed pool of capacity hours, and outcome-based agreements tied to service levels or business results. The first four all scale with activity.
That’s reasonable for both sides until change volume climbs. When a migration doubles the transports and a new AI tool adds integrations, tickets and hours grow with them, and so does the bill. ISG sees the market moving: in its 2025 Provider Lens study of AI-driven application services, it finds traditional, effort-based contracts giving way to value-driven agreements, with pricing linked to business outcomes and experience-level agreements that track user-centric KPIs alongside uptime and incident counts.
It’s worth asking a blunt question of your own contract: what does it reward when change volume doubles?
How do application management services differ from managed services?
AMS owns the business applications themselves, while managed services usually covers the infrastructure underneath them and application support covers break-fix help for users. Providers often sell all three, so the lines blur in contracts.
Application management services
Managed services
Application support
Covers
Business applications, their configuration, custom code and integrations
Infrastructure and IT operations: servers, networks, cloud, end-user devices
Help for application users when something breaks
Typical work
Incidents, changes, enhancements, performance, Basis
Patching, backup, monitoring, capacity
Ticket handling and service restoration
Measured by
SLAs per priority, backlog, availability of business processes
Uptime, response times
Ticket SLAs, user satisfaction
How do support tiers from L0 to L3 route AMS tickets?
Tier definitions vary between providers. This article uses a common four-tier convention, where each tier brings deeper skills and a narrower slice of the estate.
- L0 is self-service: knowledge articles, how-to guidance and standard requests that users resolve without contacting a support analyst. AI knowledge agents extend this tier.
- L1 is the service desk, which logs and classifies tickets, applies known fixes and routes everything else.
- L2 brings in functional and technical analysts who investigate inside the application: configuration, master data, interfaces and authorizations.
- L3 covers developers, Basis specialists and vendor support for code fixes, deep technical issues and anything that needs SAP itself.
The model works well when a problem sits inside one tier’s reach and one team’s system. Change keeps breaking that assumption. AI agents now help AMS teams resolve L0 to L3 tickets across systems, which section 8 covers in detail.
How are migrations, upgrades and AI adoption reshaping AMS workload?
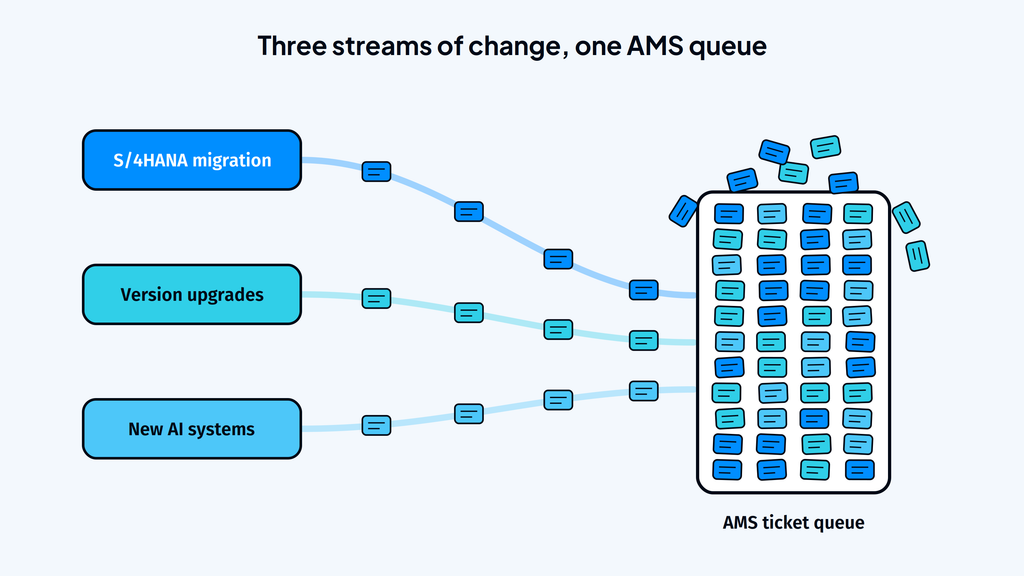
Three sources of change now land on AMS teams at the same time, and many contracts were sized before any of them arrived.
S/4HANA migrations and upgrades multiply transports and regression risk
SAP’s mainstream maintenance for SAP ERP 6.0 and the other core Business Suite 7 applications runs to the end of 2027, with optional extended maintenance to the end of 2030. That deadline is pushing migration programs through landscapes the business still depends on every day.
An S/4HANA migration sends large volumes of transports through quality and production systems, hypercare lands on the AMS team after go-live, and the work keeps coming afterward as release upgrades and feature packs each need their own regression cycle.
New AI systems add integrations and data paths AMS has to support
In a June 2025 forecast, Gartner predicted that 33% of enterprise software applications will include agentic AI by 2028, up from less than 1% in 2024. Every AI assistant, agent or analytics tool that reads from or writes to SAP becomes another integration to monitor, another set of authorizations to manage, and another place an incident can start.
Misconfigured changes are the hardest failures to trace
In the Splunk and Oxford Economics study of Global 2000 companies, human error such as misconfiguring software or infrastructure was the top cause of downtime, and the hardest to find and fix, with a mean time to resolve of 67 to 76 hours.
A misconfiguration rarely announces itself. The change that caused it passed review, the system that fails is often a different one, and the symptom surfaces in a business process hours later.
Why do tiered handoffs turn cross-system failures into long investigations?
When a failure starts in one system and surfaces in another, a tiered AMS model passes it from team to team, and each team starts its investigation from scratch.
Here’s a pattern most SAP teams will recognize:
- A transport changes a field mapping in an outbound interface.
- Orders still save in SAP, but the IDocs to the warehouse system start failing.
- The first signal is a customer service call about orders that haven’t shipped, and L1 logs “order not shipped.”
- The functional team confirms the orders look correct in SAP.
- Middleware sees failed messages and suspects bad data.
- Basis reports a healthy system.
- Only when the ticket reaches the ABAP team does anyone check recent transports and find the mapping change.
HappySignals’ 2026 benchmark puts a number on those handoffs: a ticket handled by five teams costs the employee 8.5 more working hours than one resolved on first contact. That’s the employee’s estimated lost work time, separate from how long the ticket takes to resolve.
Across the Global 2000, Splunk and Oxford Economics put the cost of downtime at $400 billion a year, about $200 million per company, with an average of $49 million in lost revenue. In the same study, application and infrastructure issues caused 44% of that downtime.
How do AI agents let AMS teams carry one investigation end to end?
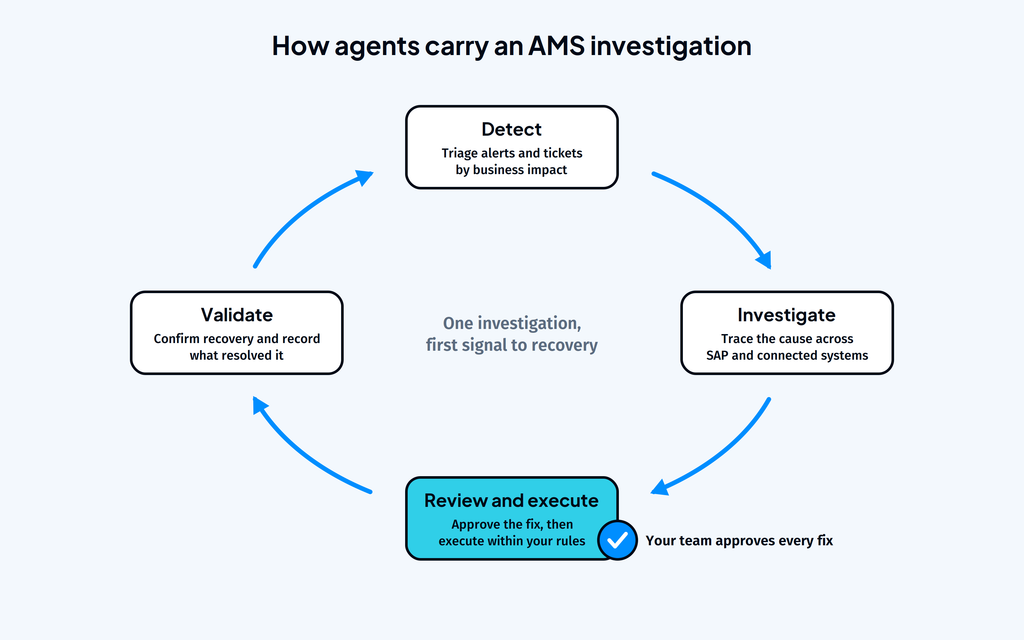
AI agents let AMS teams treat a cross-system incident as one investigation, carried from first signal to confirmed recovery, with people approving each fix. Gartner’s advice on where agents fit maps well onto AMS: use AI agents where decisions are needed, automation for routine workflows and assistants for simple retrieval. Investigating an incident that spans five systems is a stream of decisions, so it suits an agent.
Agents triage alerts and tickets by business impact
Agents read failed jobs in SM37, short dumps in ST22, spool queues and incoming ITSM tickets as they arrive. They assess severity and identify the affected systems and business processes, so the team starts each shift on the issues that cost the most.
Agents trace failures across SAP and connected systems
An agent follows the evidence wherever it leads: logs, custom ABAP code, configuration and recent transports inside SAP, then into integrations, infrastructure and downstream applications. In the warehouse example above, one investigation connects the failed IDocs to the transport that changed the mapping. The agent shows the supporting evidence and prepares a proposed fix with validation steps.
Agents score change risk before CAB
Prevention matters as much as resolution when change volume climbs. Before a change reaches the board, an agent maps the changed objects, dependencies and affected systems, identifies implementation, rollback and downtime risks, and produces a risk-scored CAB briefing with testing and approval checklists.
People approve every fix, and agents confirm recovery
Agents work read-only by default, and every write action needs explicit approval. Once the team approves, the agent executes the change within your governance rules, reprocesses failed transactions, checks the results against recovery criteria, updates the ITSM record and notifies stakeholders, so the knowledge of what fixed it is recorded for next time.
This is how Lightrun’s AI agents for application management services work across SAP and connected systems. Lightrun’s Forward Deployed Engineers customize the agents to each landscape, including legacy systems, legacy code and non-API platforms, and permissions, RBAC and audit logs keep the AMS team in control.
Classic AMS
Agent-assisted AMS
Unit of work
A ticket, passed between tiers
An investigation, carried end to end
Cross-system failures
Handed from team to team
Traced across systems in one investigation
Change review
CAB preparation assembled by hand
Risk-scored briefing before every change
Evidence
Rebuilt by each team that picks up the ticket
Collected once and attached to the record
People
Investigate and execute
Approve, decide and handle the exceptions
Measured by
Ticket SLAs
Ticket SLAs plus business recovery
How do you know if AI in AMS will deliver value?
In the same June 2025 forecast, Gartner predicted that over 40% of agentic AI projects will be canceled by the end of 2027, citing cost, unclear value and weak risk controls, and estimates only about 130 of the thousands of vendors claiming agentic AI offer the real thing. These five questions separate an agent that will hold up in your estate from a chatbot with a new label.
- Does it work read-only by default, with approval before every change and a full audit trail? Governance decides whether the business lets an agent near production at all.
- Does it reach past SAP into integrations, infrastructure and downstream applications? Cross-system failures are where AMS time goes, so an agent confined to one system repeats the handoff problem.
- Does it fit your current team and provider? The fastest value comes from agents that plug into the queues, tools and approval flows you already run.
- Can you measure it on outcomes the business recognizes? Recovered transactions and avoided failures make a stronger case than tickets closed.
- Does it act, or only answer? An assistant that summarizes logs saves minutes; an agent that investigates, prepares the fix and verifies recovery changes how the team works.
Measure AMS by business recovery alongside ticket SLAs
Ticket SLAs still matter, and a few additional measures show whether the team is keeping pace with change.
KPI
What it shows
Why it matters as change volume grows
Mean time to resolve
Time from first signal to confirmed recovery
Captures the full investigation, including every handoff
Reassignment rate
Share of tickets that change hands at least once
The most direct measure of cross-team friction
Change failure rate
Share of changes that cause an incident
Shows whether review before CAB is preventing failures
First-time-right fixes
Fixes that hold without the ticket reopening
Separates root-cause fixes from workarounds
Failed transactions recovered
Orders, invoices and messages restored after an incident
Ties AMS performance to business outcomes
How does AMS keep pace with change?
Change will keep arriving through migrations, upgrades and new AI systems. AMS teams that treat it as their main workload, review each change for risk before it lands, and hand the cross-system investigation to agents give their specialists more time for the decisions that need them.
See how reliability agents keep AMS in step with change
Frequently Asked Questions
AMS stands for application management services: the ongoing support, maintenance and improvement of an SAP landscape after go-live, including Basis, functional and custom code support.
AMS contracts are commonly priced by effort: dedicated FTEs, time and materials, ticket volumes or fixed capacity. Outcome-based models, tied to service levels or business results, are growing as AI changes how the work gets done.
AI agents analyze transports and dependencies before a change reaches CAB, trace failures across SAP and connected systems after it lands, and execute approved fixes. That helps the AMS team absorb migration, upgrade and new-system change with less manual investigation per incident.
AI agents work alongside your AMS team or provider. They take on investigation and routine execution, while people keep the approvals, judgment calls and relationships with the business.